Site: Alpine Elementary field
Weather: Overcast, calm winds during flight, weather at KCOLONGM64 51.5f 29.97 in 6.7mph 49%RH
Hardware: Rocketometer6050 #2, Estes Star Stryker (modified)
Forgot
to pull cap from launch rod before flight. Flew straight, seemed to turn level to ground at
apogee, I could see a yellow tinge to the tracking smoke. Parachute
ejected but never inflated. Rocket fell free from apogee. Rocketometer
was still running after flight. Engine hook unzipped about 1/8 inch to
the aft, probably due to ejection. One fin has a cracked glue joint.
Minor ding to rocket nose
cone due to striking launch rod cap. Rocket could probably be repaired, but not reflown in its current
condition.
No video of the flight was captured. I had the camera, forgot to press record.
Rocketometer has one file as expected, RKTO0500.SDS
35,369,984 bytes. Indicates that Rocketometer was running through whole
flight.
Switch and card not glued into place. Reset solder bridge in place. Rocketometer ran through flight anyway, indicating that nothing was jarred loose.
Rocketometer on internal power ~11:50am
Nautilus reports weird file sizes for files. fsck.vfat does not report any filesystem errors.
Total packets retrieved: 1,572,103 AD377 STRUCT = -> <Anonymous> Array[124694] BMP2 STRUCT = -> <Anonymous> Array[6234] DEF STRUCT = -> <Anonymous> Array[15] DUMPDATA BYTE = Array[65640] F STRING = 'RKTO0500.SDS' HMC STRUCT = -> <Anonymous> Array[124694] INF LONG = 100 MPU STRUCT = -> <Anonymous> Array[1246947] N_EXTEND LONG = -59604 N_PACKETS ULONG = Array[2048] OUF LONG = 100 PKT STRUCT = -> <Anonymous> Array[1] STATUS INT = 0 TCC STRUCT = -> <Anonymous> Array[68932] T_PACKETS ULONG = 1572103
Greater than 26 minutes of data recorded. Processing took about 14 minutes.
Time stamp difference between first MPU record and last: 1601.1205s (26m41.1205s)
Range zero is 1058s (last top of second before first acceleration)
MPU did saturate during boost
Rocketometer loaded and ready for flight
Flight battery is similar to this, not visible in rocket pictures since it is packed in foam behind the board. Photo from Sparkfun Electronics published under CC BY-NC-SA 3.0
Red circle - Mars impact locus. Green star - old nominal approach. Black ellipses - old 1,2,3 sigma. Blue dots - new Monte Carlo samples. Orange rings - new 1,2,3 sigma ellipses according to Monte Carlo
They finally published a new set of observations, and based on that, it is now the three-sigma ring which touches Mars, not the 1-sigma ring. There were zero samples in the Monte Carlo which impacted Mars, so there is less than a 1 in 5000 chance of impact.
B plane plot -
Red circle is Mars, green star is most likely trajectory (miss by
55000km), black ellipses are 1,2,3 sigma direct from JPL Horizons, blue
dots are 3,892 Monte Carlo samples
What's in a name?
First off, the name is C/2013 A1, which means that it is a C/ non-periodic comet (this is the first recorded observation of the object) 2013 A discovered in the first half of January 2013, 1 first comet discovered in that part of the month. Siding Spring is parenthetical and not part of the name, just the name of the observatory that discovered it, but since it's easier to remember than a number, we will probably end up hearing a lot about comet Siding Spring.
Why do we care?
The comet is on a very close-approach to Mars. We care about Mars because we care about the spacecraft present in orbit and on its surface. Even more interestingly, the 1-sigma uncertainty ellipse currently includes Mars. There is about a 1 in 1000 chance of impact.
What are its effects likely to be?
If it hits Mars, it will almost certainly throw enough junk into low Mars space to kill all the spacecraft in orbit. It is also likely to kill any rover which happens to be within several hundred kilometers.
If it misses, well it's a comet visible from 7+ AU out. It's going to be a big'un. All the usual stuff that applies to comets will apply here. It is likely that Mars (and therefore all the satellites) will pass through the coma, and be subjected to a pretty good sandblasting. We will need to review our experience with the Halley armada, and consider that the closer-passing objects were armored.
If we decide that the comet is a hazard to spacecraft and other mechanical things, we have to decide what to do with Maven. Do we hold it until the next window? Is it worth firing to get a month's worth of data?
Details
I have been watching this for the past week, and while refined orbits have been produced, the nominal miss distance has been shrinking, and impact has not been excluded yet. The last solution I have seen gives a 0.016% chance of impact.
In particular, Horizons says that the 3-sigma uncertainty ellipse has a semi-major axis of 88000km, a semi-minor axis of 22000km, and that the smallest uncertainty ellipse which touches Mars has a value of 0.98 sigmas. Further, the ellipse is rotated 24.20deg from the line between closest approach. I ran all this through an IDL script and got the plot at the top of this article.
I believe that the documentation on Horizons is wrong, and that what is documented as the 3-sigma uncertainty ellipse major and minor is really the 1-sigma ellipse. With this change, the Monte Carlo samples (see below) match the error ellipses well. Otherwise, I can't reconcile the 3-sigma ellipse touching Mars with the reported Nsigma of 0.98.
A new and powerful tool
The Minor Planet Center collects observations, and in principle you can fit those observations yourself, if your name is Carl Friedrich Gauss. Or if you get Find_orb from Project Pluto. I'm still learning it myself and playing with it, but it has the ability to import observations in MPC format. The program is under active development, and appears to have accreted features as interesting real-world events have happened. For our purpose, the two best features are auto-fit and Monte Carlo. The latter is done in an especially clever way. The program creates a cloud of objects, but it doesn't require a covariance matrix. Instead, it adds a bit of noise to each observation in RA and Dec, then fits an orbit to those new observations and creates an object.
So, I got the observations for C/2013 A1 and dropped them in. After 5015 Monte Carlo samples, 7 of them hit Mars, for an impact probability of 0.14%, quite in line with the JPL Horizons number, but produced directly and solely from the observations. As seen above, they almost perfectly fit the JPL Horizons ellipses.
type 2012 DA14, and say yes to do a name search. Once it finds it, type s to get an SPK kernel. Give the following answers:
SPK text transfer format [ YES, NO, ? ] : n
SPK object START [ t >= 1900-Jan-01, ? ] : 2013-Feb-01
SPK object STOP [ t <= 2101-Jan-01, ? ] : 2013-Mar-01
Binary SPK will be created, you will be asked to add more objects, say n.
Now you will get a download link, copy it to your browser and save it. It will be named something like wld17761.16.
2) Install Celestia
3) Create an extra for Celestia
Create a text file 2012_DA14.ssc in the extras folder and create a data folder within that folder. I needed to run a text editor as administrator to do this.
In the text file, paste the following text: "2012 DA14" "Sol" { Class "asteroid" Texture "asteroid.jpg" Color [ 1.000 0.960 0.919 ] BlendTexture true Radius 0.025
4) Copy the spice kernel wld12345.16 to the extras/data folder and rename it 2012_DA14.bsp
5) Start up Celestia and look for 2012 DA14 in the solar system browser. It should be the last item under Sol. If it's not there, use ~ to bring up the debug screen and up and down to scroll it, and see if there are any errors for 2012 DA14.
Closest observed distance is just under 30000km. It travels from south to north past the night side of Earth.
The Big One, by Stuart Slade. World War II went very differently, with England basically surrendering after Dunkirk, immediately drawing the USA into the war. With the Western front secure, Germany was able to focus on the Russian front. They captured Moscow (and killed Stalin, good riddance) but were stopped short of the Urals by the combined Russian and American armies, where they stalemated for five years.
One day in 1947, that changed. On that day, over a thousand planes were launched from bases all along the East Coast of the United states, carrying over 200 Mark III atomic bombs. These were upgraded from the Mk3 used in our timeline, with a typical yield of 35kT instead of the 20kT of Trinity and Fat Man. The main bombers were B-36s, with four bombs each. Each bomber had two escorts, also B-36s.
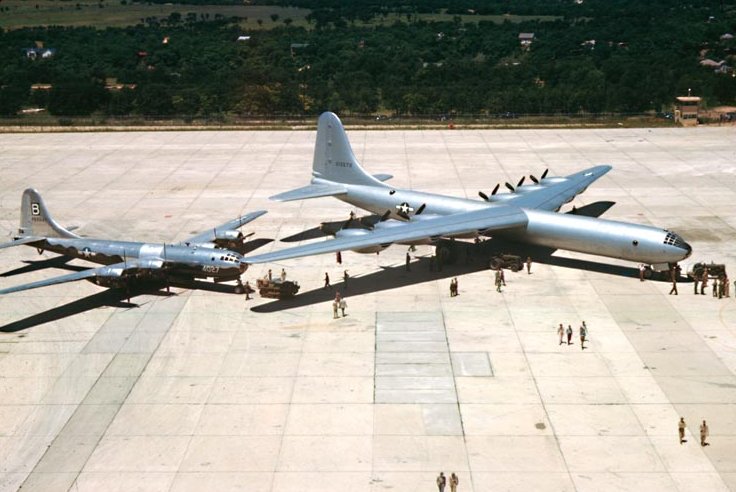
That smaller plane to the left is a B-29. To put it mildly, the B-36 is a large aircraft.
Interestingly, once the bombers were over Germany, they turned on Salvage Fuses, which would set the bombs off once they reached 2000ft, even if still in the plane. So even shooting down a bomber won't save you. In fact, the second blast was due to this very effect. That's just mean...
One hundred fifteen bombs are accounted for in the book, including twelve for Berlin, eight for Munich, and twenty-five between Dortmund and Bonn. Two were in the Frankfurt area, one in Koblenz, one in Heidelberg, but none in Rothenberg. Estimated casualties are twenty million immediate fatalities and probably that many again from radiation, lingering injuries, illness, and the collapse of civilization and famine caused thereby. The population of Germany was about 60 million in 1945, real world timeline.
It's an interesting story, but it has some holes in it, like how in the world did General Groves keep Manhattan secret for two additional years while they built up the stockpile? I got the book largely to see the answer to that question, but I didn't find it. Also, I am surprised they didn't base in Russia. However looking at the map, it is almost as far from the Front to Germany as it is all the way from America.
But none of that is the Gem. I found out about the Big One on the TV Tropes Wiki in late January, and after failing to find the story in free form on the net, I decided to shell out and buy the book on Friday, 1 Feb 2013. The last page of the book is marked:
Made in the USA
Lexington, KY
02 February 2013
The book was made after I ordered it. It seems that it was literally made for me.
Of course I am designing a Rocketometer around the Propeller. How could it be otherwise?
In doing so, I have to get my own parts. The Sparkfun breakout is an interesting jumping-off point, but they don't even use bypass caps, so I added a set of those. Also one thing which concerns me about this whole endeavor is that all the memory is limited. Each cog gets 2kiB, for a total of 16kiB, but the images for each cog must be stored in main memory, which has 32kiB of RAM and 32kiB of ROM. There is no way that I am going to be able to get the program source code embedded with that little amount of memory.
This brings us back to the EEPROM on the breakout board. The bootloader burned into the Propeller knows how to bit-bang an I2C interface and read a memory on the bus. It treats the memory as a 32kiB byte-addressable memory with auto-increment, so it can set an address once, then read and read and read and fill main RAM. The Propeller documents say to use a 24LC256 or similar, so I got to looking at Digikey to see if they had that chip, and perhaps more interestingly, if there was a bigger chip which would still work. It turns out that the design of the EEPROM is the gem of the week.
First, the hardware. The 24LC256 is a 256kib memory organized as a 32ki x 8 (byte-addressable) memory. It is in a kind of large package, a whopping 5mm wide, with 8 pins. This is a lot for a device which is I2C and could in principle work with only 4 pins. But here is the cleverness. The device has three address pins, allowing the 7-bit I2C address to be anything in the range 0x50-0x57. So, you could just stack up to 8 devices on the bus, with only the address pins different, and get 32x8=256kiB of memory, at the cost of using 8 devices.
The 32kiB space is addressable with 15 bits, but the I2C protocol is
byte-oriented, so you have to send 16 bits, of which only A0-A14 are considered, and A15 is ignored.
These facts work together to allow the address space to be easily extended. First, a 64kiB part is doable just by considering A15 in the address. Next, a device can internally answer more than one address, for instance by ignoring the A0 hardware pin and answering both 0x50 and 0x51. This of course means that you have to readdress the device when you cross from the address space covered by 0x50 and the one covered by 0x51. You would have to do that anyway if there were multiple real devices.
This all adds up to the STMicro M24M02, which appears to be compatible with the 24LC256, in that if you talk to an 'M02 like a '256, it will answer like a '256. So, you can use the larger device and the bootloader should happily just work. However, it is a 2Mib memory organized as 256ki x 8 (256kiB), eight times as much memory as the reference design, and approaching comparability with the LPC2148 and its 512kiB of Flash. Then when your application takes over, you can use your own bit-bang to access the full chip.
The 'M02 still has one address pin, so in principle you could make a 512kiB memory in 1 chip without changing anything. Going beyond this will break the nice de-facto protocol going on here.
I write this before ever using one, so consider this a review of the concept rather than the implementation. The Parallax Propeller is a microcontroller with a couple of interesting features, and perhaps more interestingly, a couple of intentionally missing features.
First off, it has no peripherals other than 32 GPIO pins.
Secondly, it has no such concept as interrupt.
Thirdly, it has eight independent processors, called "cogs", each with its own memory. Each one can run on its own resources without interfering with any other processor. Each cog is a 32-bit processor, and gets access to 2kiB of ram, shared between code and data.
Fourth, it has a set of resources that all processors can access, called a "hub". This basically consists of more memory and a round-robin memory controller which each cog can access in turn. The hub has 32kiB of ROM with the bootloader, Spin interpreter, and a couple of tables, and 32kiB of RAM.
The missing features are what make the controller interesting. Want an I2C? Write a program for a cog which can bit-bang it. Same for SPI, UART serial, etc. Presumably it could bit-bang low-speed USB, but high-speed would be difficult due to limited processor speed.
Further -- want an interrupt? Too bad. Instead, assign a cog to sleep-wait for the appropriate signal.
Programming such a beast is clearly a different problem than programming an ARM of any flavor. ARMs are all about peripherals, registers, interrupts, etc. Propeller is about bit-banging. Effectively you can use a cog as a soft-peripheral to do basically any digital process.
As I mentioned above, the processor comes with a Spin interpreter. Spin is a custom language for programming Propeller, which gets compiled into byte code and interpreted with the Spin virtual machine. Of course you give up performance, but they used an interpreter in the Apollo Guidance Computer. There, it was for memory saving - a single interpretive instruction could take the place of many instructions in AGC machine language. They gave up time to gain space. Spin could have similar benefits, but it seems like the main purpose is providing a language which natively handles the very different concepts needed to handle a processor as weird as the Propeller.
A Propeller program then consists of a bunch of Spin and machine language routines, all stored in hub RAM and copied from some external source whenever the chip resets. Aside from self-modification or using a cog to bit-bang a memory bus, this is all the space you get. This is a rather tight restriction, in fact less memory than in the AGC. But, they fit a full-blown Kalman filter into that.
Of course I have already designed it into a Rocketometer. It's what I do. One of the great things about the GPIO and bit-banging style of the Propeller is that I can put the SPI bus on the pins which are closest to their targets outside the chip. This makes routing the board MUCH easier.
So I will say for now that Propeller shows a lot of promise. The design is a gem. We will see about the implementation.
Wonderduck has decided to drop Ben-To, which I only downloaded and watched on his recommendation. Thanks for that... Although I guess writing a careful episode-by-episode writeup isn't really a recommendation from him -- consider Rio Rainbow Gate, where it is more like a warning.
Anyway, the Anime of the Week then is Vividred Operation (vivid-red, in case you miss the space and can't parse the title). Episode 1 established that it was that kind of show. I mean magical girl -- what were you thinking of? Even though it is technological magic, it was still magic, since they still had the magical clothing change transformation sequence. That's right, the defining characteristic of a magical girl is magical clothing change.
Episode 2 can be subtitled "Friendship is insufficiently magic".
I thought about doing an episode writeup, but I only thought of a couple of jokes, and Wonderduck got them himself, so I will restrict myself to what I can do -- one line jokes.
Episode 3 features them skipping directly to "Form Blazing Sword", a clear violation of protocol since you are supposed to wait until you are almost defeated before pulling out your game-changing weapon.
Recently there was a severe shortage of apple cider here in Ponyville, which we had the opportunity to remedy, but because of short-sidedness on the part of some of your subjects and your apparent policy to grant monopolies in too many areas of the market, we chased that opportunity out of town.
In Ponyville, the cider franchise is granted to the Apple family of Sweet Apple Acres. Their orchard is a relatively small business and is incapable of supplying the demand. Cider prices are also too low, due to your policies of price control on cider, so the Apples are losing out as well. As a consequence, hundreds of ponies, a good fraction of the citizens of
Ponyville, are deprived of cider, and those that do get it are forced
to pay for cider with their time rather than with bits, by camping out at the gate. The time that they are granted, all those moments that will never exist again, they were forced to spend waiting rather than doing what they wanted.
If it seems cruel and heartless to give priority to ponies just
because
they have more bits, consider that your current policies are cruel and
heartless as well to those who don't get any cider because they don't
have as much time to waste in line. Even those ponies who do choose to
spend those moments that will never exist again, pay for cider with both
bits and time. Those customers spent that time to no benefit to anyone
-- not themselves, and not the Apple family. If time were bits, it is as if those bits of
time were carefully collected, from both the ponies who got cider and
those that didn't, and dropped into Tartarus, never to be recovered, and
never doing any pony any good. Even worse, those ponies who don't end
up getting any cider pay time
for cider they don't get.
A pair of entrepreneur ponies, the Flim Flam brothers, tried to remedy this, but because of the cider monopoly, they were unable to simply purchase the Apple family apples as a raw material and make the additional cider the market demands. The new business attempted to enter into collusion with the established players, but were unable to negotiate a cartel, which may have been even worse than the monopoly. By denying market competition, they were forced to compete in other ways, in this case a single-elimination to-the-out-of-business contest of pure quantity of production, rather than the ability to satisfy customer demand. In this competition, the Apple family was forced to work far beyond its sustainable capacity to near-exhaustion, and the Flim Flam brothers were forced to compromise their quality control, leading to inferior cider and tired, thirsty ponies.
If your policy of granting monopoly franchises was rescinded, the Flim Flam brothers could have just purchased apples from the Apple family or other suppliers at the market rate, and the Apples and Flim Flam could have worked together without having to collude. If your policy of cider price control was rescinded, the Apples could have raised the price of their cider to the point that some ponies would have decided that the cider wasn't worth it. The same number of ponies would have been served, the Apples would have made more money, and those ponies at the back of the line but more willing to pay would have been able to get their cider. With another supplier, more ponies would have been able to be served, and even if Apple family cider is better than Flim Flam cider, something is better than nothing, and the market would have decided that Apple family cider was worth more, and would have paid more. Those unwilling to pay that much would have been able to pay less to get Flim Flam cider.
They call it capitalism, but it isn't really an -ism of any kind, just the invisible hoof at work, ponies working towards their own benifit but supplying the needs of all ponies.
Please consider changing your economic policies to allow freedom to your subjects to pursue the interests that seem best to them.
It's a new world with tons of cider, fresh squeezed and ready for drinking -- and also plenty of quills, sofas, anemometers, and maybe even things nopony has even thought of inventing yet, but would if they had time to think and invent instead of waiting in line for cider.
The Pythagorean theorem is one of those gems that I won't go into a lot of detail about, because it has been so well-covered before by others. Let's just say that it is a property of Euclidean space, in particular a consequence of the parallel postulate. I just mention it here because it is an example of a topic I am going to go over in great detail.
In 2D Euclidean space, we can figure out the distance of any point from any reference point by setting up a rectangular coordinate system with the reference point at the origin. If there were just two points we cared about, we could align the axes such that the X axis went through the other point, and then we could just read the distance off that axis. That's not really exploiting 2D space, so we will think about one reference point but lots of other points all over the plane. We can use the Pythagorean theorem to measure the distance from the origin to any point in the plane:
\[s^2=x^2+y^2\]
With this coordinate frame you can figure the distance between any two points, even if one is not at the origin, as follows:
\[s^2=(x_2-x_1)^2+(y_2-y_1)^2\]
By using the standard delta-notation from engineering, we can simplify this back to
\[s^2=\Delta x^2+\Delta y^2\]
Now what is true for 2D Euclidean space is also true for 3D. The Pythagorean formula works, you just have to extend it to cover the third dimension
\[s^2=\Delta x^2+\Delta y^2+\Delta z^2\]
Those crazy topologists have generalized the Pythagorean theorem to
fit their weird bent rubber spaces. They say that any space, along with a
function which takes two points as an argument and returns a number, is called a metric space, where that function is called the metric. The metric must obey certain axioms, most important of which is commutativity - the distance from point A to B is the same as the distance from B to A.
Some of the topologists twisted imaginings don't really admit such a thing as a straight line. They get around this by saying that if you look at any small enough piece of the space, it is close enough to flat that we can define a metric there. Some spaces are so bent as to not even permit this, but those spaces which do, are called manifolds. In a manifold we talk about points which are close together, and represent this in our metric with differential notation
\[ds^2=dx^2+dy^2+dz^2\]
Now on a manifold we can specify a series of points to draw a path through, find the distance between each, add them all up, and get the length of the path. In calculus-speak, we have every point on the path, and we integrate along the curve to get the distance. However for flat space, there is such a concept as a straight line, and it is the shortest distance between two points. If you take the delta-form above and integrate the differential form, you end up with the same thing. Because of this, we will just show things in differential form from now on.
The film Dimensions
is all about extending the same concept to four- and higher-
dimensional space. All the Euclidean axioms apply, and the fourth
dimension is exactly like the other three, so it works into the metric
the same way:
\[ds^2=dx^2+dy^2+dz^2+dw^2\]
One narrator talks about how 4D space is the prettiest, because it contains such things as the 24-cell. Also he says that it may be because real physical space is 4-dimensional also once you consider time. Blah blah Einstein aggressively ignore history blah blah blah. Spacetime is 4-dimensional, but here's the weird part.
Time is not the same as Space.
"Wait a minute" I hear you all saying - "Obviously time isn't the same thing as space. Duh." But, the whole reason we call time a dimension, and the same reason we don't call temperature a dimension, is that there are coordinate transformations that mix in time with space. I'm going off of memory, but this argument came to me through a little book called "Relativity and Common Sense". For instance, imagine a plane where every point is painted a different color. So, at each point we can measure three things, its x and y coordinate, and its color. If we rotate the coordinate frame, we mix together the x and y coordinates
But, there is no rotation, no coordinate transformation which preserves our understanding of what coordinate transformation means, which can mix color and spatial coordinates. Color is not a dimension in this sense.
Well, Time is.
The transformation isn't just a rotation, but the Lorenz transformation from coordinates measured by one observer to coordinates measured by a relatively moving observer, depends on the relative speeds of the observers. And here's the weird thing - time is a dimension, but it is not just like the other three dimensions. In fact, the metric for the spacetime observing the Lorenz transformation is called the Minkowski metric, and it looks like this:
\[ds^2=dx^2+dy^2+dz^2-dt^2\]
See the minus in the time term? It says that the longer the time between two events, the shorter the distance, all other coordinates being equal.
It gets weirder than that. If the time difference is long enough, it drags the whole right side negative. The squared distance between two events is negative. The distance between two events is imaginary. In special relativity, we say that when \(ds\) is real and positive, it is called proper distance, and it is the distance between two events as seen by some observer who sees them happening at the same time. Further there is no way for a single observer to be present at both events without exceeding the speed limit in the space, which introduces its own problems. When \(ds\) is imaginary, the (real) coefficient is called proper time, and represents the time interval between two events as seen by an observer who sees them happening in the same place. A single observer can be present at both events without exceeding the speed limit.
See what I mean by weird? In Minkowski space, there is a speed limit imposed as part of the fundamental geometry of space. If we though of time as just a dimension like space, this is equivalent to saying that it is impossible for a line to exceed a certain slope (change in space dimension per unit change in time dimension). No such limit exists in Euclidean space. Spacetime is 4D, but not Euclidean. It is not the same 4D space discussed in Dimensions. The Pythagorean theorem is false, and therefore the parallel postulate is false. Minkowski space is the only flat (metric works across long distances) space I know of which is non-Euclidean.
Now the question is, are the regular polytopes the same in Minkowski space? Does it make sense to talk about polytopes? Is a polytope regular from one point of view but not from another? These and other questions can be answered by the Minkowski metric, but I don't know the answers. I was only recently even able to form the questions.
I had been keeping this quiet, but it is the natural culmination of all that I have written on this blog.
At my day job, I work with space projects, but I have only been in the same room as flight hardware once, and that was purely as a tourist, to get my picture taken with it. I have written code that has gone into space, but never touched the hardware that carried it.
In October 2013, that will change. I am building space hardware. In a sense, that has already changed, since I have touched the hardware, but it's not space hardware yet. I have arranged for a version of the Rocketometer to fly on a rocket all the way into space.
The people I work for at my day job run an instrument in space that needs to be calibrated every so often. Every year or so, we fly a sounding rocket with a copy of our instrument, pop it up above the atmosphere for a few minutes, then let it fall back down into the atmosphere and descend on a parachute. It goes into space (well over 100km) but not into orbit.
On the campaign building up the rocket for the last flight this past summer, I was tinkering with my rocketometer (actually the 11DoF) and got to talking to my scientists about it. I told them about my daydream to actually get this thing on the rocket, and they said it was a great idea. Naturally it was far too late to get on board that last rocket, but with this next one I have plenty of time, especially considering that the hardware is finished, and I potentially could fly it now. The baseline mission is just to collect the data as fast as possible, and not bother with any on-board processing. That code was demonstrated with the speed test I did a few weeks ago.
My test plan and to-do list then looks like this:
Adapt the old code to the new hardware. A couple of the I/O lines were reassigned to simplify the board design.
Write an offline Kalman filter to process the data. IDL will work fine for that. Mostly I just need a set of equations of motion that allow the compass, gyro, and accelerometer to calibrate each other.
Calibrate the sensors. I have an old record player with no needle which will be perfect for this. I may be able to use some stuff in the labs at work to help with this.
Do a test flight in a model rocket. These generate a similar scale of forces and rotation rates, just for much shorter durations, seconds rather than minutes. The Rocketometer was designed to be carried in any rocket with a payload section 1" or larger in diameter.
Get USB Bootloader++ working. This is low priority, as I can program the part over serial as I have been doing for a while.
Consider on-board processing of the data.
I will be using the Rocketometer2148 with an MPU6050 6DoF sensor, an ADXL377 analog high-g accelerometer, an AD7991 12 bit ADC to read it, an HMC5883 compass, and a BMP180 pressure/temperature sensor.
With a couple of changes to main.cpp and gpio.cpp to tell it where the sensors and lights are on this board, the thing works! It may also be working at my goal rate of 1000Hz, attributable to a faster SD card, reading the compass only 1 of 10 times that the 6DoF is read, and not reading the HighAcc.
I can get an MPU6000 from Newark for about $39, or I can get an MPU6050 from Sparkfun for about $20. The only issue with the 6050 is that it runs on I2C, and maxes out at 400kHz. In burst mode, I can get a byte across in 9 clock cycles. An MPU6050 readout has three 16-bit gyro registers, three 16-bit acc registers, and a 16-bit temperature readout, a total of 14 bytes, plus addressing the part, for 15 bytes. Nine cycles each gives 135 cycles, plus a couple more for starts and stops, call it 140 cycles.
Is this enough? Of course not. There is never enough bandwidth. But is it enough? In 1 millisecond, there are 400 cycles, so in theory the MPU6050 being read at 1000Hz will use up 33% of the available bandwidth.
Now there is also the high-accelerometer, read out using an I2C ADC. The ADC has three 16-bit data registers, so 7 bytes counting address. 7 bytes at 1000Hz, call it 70 more cycles. Now we are at 52% bus usage. We need to throw in a compass read and pressure sensor read every once in a while, but it looks like enough to run the sensor at whatever rate I want.
So maybe there is enough. One way to get more bandwidth is to use the other I2C bus on the chip, but this involves a fairly heavy redesign of the board. We would put the MPU and compass on one bus, and the HighAcc and pressure sensor on the other bus.
Onto the measurements. I put together a program which reads the sensors with no delay, in effect as fast as possible with blocking. The program records the tick count (TC), which increments at 60MHz, before each reading, then reads the ADXL345, HMC5883, MPU6050, and L3G4200D in that order. So, the time spent doing the ADXL345 read is the TC of each HMC packet minus the TC of the corresponding ADXL packet, and so forth. The ADXL345 consistently takes 131 microseconds with a variation of less than 1 microsecond. The HMC takes 483 microseconds. And for the moment of truth, the MPU6050 takes 539 microseconds. All is fine and good, right? Nope. We spend most of our time waiting for the card to write out. On a good write, it takes 9 milliseconds, 18 times longer than an MPU read, to write a sector to the SD card. A lot of that could be gotten around by not busy-waiting for the card to finish.
In any case, there is plenty of bandwidth for the sensors, so there is no point in splitting up the traffic to two I2C buses. Reading twice as many sensors as necessary and producing more data than necessary (the real rocketometer will only carry one set of gyros), it still is reading out at about 300Hz.
The experiment that I wrote about yesterday was actually carrying two gyroscopes: The one in the MPU6050 discussed then, and the L3G4200D on board the 11DoF. This gyro was connected to the Loginator by SPI running at 1MHz. The 11DoF tab was oriented such that during the South integration, +X was East, +Y was Up, and +Z was South. In the same integration, the MPU tab was oriented such that +X was West, +Y was South, and +Z was Up (not Down as marked on the board -- the silkscreen is wrong, proven by the positive signal on the +Z MPU signal.)
So, we match up axes as follows:
MPU6050
11DoF
+X
-X
+Y
+Z
+Z
+Y
Therefore we just perform the calculation using +Z on the 11DoF just like yesterday we used +Y.
The result doesn't look so good. First, data from yesterday, showing what a detection looks like:
This shows 1 minute of data from before and after the rotation. The noisy part on both ends is 10 seconds of raw data, and the smoothed bit in the middle shows a 2000-sample (roughly 20 second) boxcar smooth. The white data was with +Y pointing north, and the red data was with +Y pointing south. In that middle region, the difference is due to the rotation of the Earth.
Now, the data from the L3G, also taken yesterday, but not reduced until today.
Since the signals cross, there is no clear detection, even with a 20 second boxcar average. Why not? As it turns out, this sensor was set to 2000°/s, its least sensitive setting, with 1/8 the resolution of the MPU. So, it's not a fair test.
Abstract: An MPU6050 6DoF MEMS sensor is used to measure the rotation of the Earth. The device is run pointed north for 1 minute, then south for 1 minute, taking 98samples/s during the runs. Actual rotation difference between north and south is 0.0063837°/s, taking into account the cosine(latitude) effect. Measurement is 0.0064822°/s±0.0015299°/s, representing a clear detection of the rotation. The MPU6050 gyroscope is extremely accurate, probably sufficient for the Rocketometer mission.
This is also a review of the MPU6050 6DoF sensor. This part has a three-axis accelerometer with ranges ±2g, ±4g, ±8g, and ±16g, and a three-axis gyroscope with ranges ±250°/s, ±500°/s, ±1000°/s, and ±2000°/s. Since the intended mission is flying on a rocket, and certain rockets that may fly with this have been observed to accelerate at around 25g, it will need to be supplemented with a high-accelerometer, but the gyroscope will handle the 4.5Hz rotation expected.
The earth rotates 360° in 24h*60m*60s=86400s, or 1° in 240 seconds, or 0.00416666°/s. The gyroscope's most sensitive setting is ±250°/s and reads out at 16 bit resolution, resulting in 500°/s/65536DN=0.0076294°/s/DN, not quite enough to distinguish earth rotation from a standing stop, but enough to distinguish when one axis is pointing north, then south. Unfortunately, that presumes that the gyro is noise-free, which we will soon see is false.
The current experimental setup is on a breadboard connected to a version 1.1 Loginator by I2C at 400kHz, carefully aligned to true north by the following extremely accurate procedure: Since the walls of the secret underground laboratory are not aligned with true north, I pulled up the Google map of the lab and oriented the map such that the walls on the map were parallel to the real walls. The case of the phone was then aligned to true north. I put down a line of tape to mark this orientation. In this setup, the MPU6050 axes were aligned with +Z pointing down (thus we expect to see the 1g field read negative), the +Y axis pointing north first then south, and the +X axis pointing east first then west.
Of course, all measurements are contaminated with noise. This can often be beaten back by taking many measurements of the same thing. If you take into account a number of simplifying assumptions, the noise of the average of \(N\) measurements of the same quantity is \(\sigma/\sqrt{N}\). In short, if you take 100 measurements of the same thing, the average of them is expected to have 1/10 the noise of the original measurements. My previous efforts have taken data over very long stretches of time, hundreds of samples per second over hours. This time I decided to take data for 1 minute at a time. I sampled at 98samples/s (2samples/s were spent reading the pressure sensor, a topic for another day) for 1 minute with the Y axis pointing north, then 1 minute with the Y axis pointing south.
The estimated noise on each measurement, calculated with the standard deviation of all the measurements, was 11.02DN, or 0.084°/s, about 20 times that of the rotation of the earth, so it is obviously impossible to measure with one sample. But, I took 5880 samples, giving a predicted noise on the average of 0.14DN or 0.001°/s, plenty small enough to measure the rotation of the Earth. But did I? And if I did, why did I fail before?
Data:
Y north: -0.2217195°/s±0.0010972°/s (1σ)
Y south: -0.2282107°/s±0.0010972°/s (1σ)
Difference: 0.0064822°/s±0.0015299°/s (North is greater than South by this much)
Now, what is the expected value? First, is it positive or negative? Relative to inertial space, the device is rotating according to the right-hand rule around the Earth's axis. The device measures a right-handed rotation around an axis as positive, so the device should read more positive when pointing north than when pointing south, as it does.
Also, as mentioned above, the earth rotates at 0.00416°/s, but my Y axis is inclined 40° relative to the earth's rotation axis, so I should only expect to see \(\cos 40^\circ\) as much. Also, I would expect to see twice as much as that, because I am not comparing a standing stop to rotation, but rotation one way to rotation the other way.
Taking all this into account, the predicted measurement is....
0.0063837°/s.
My measurement clearly brackets this. In fact, the measurement is much better than I have any right to expect, being only 0.06σ above the expected value. I would have accepted any measurement with the proper sign and an error of less than 1σ.
Why did I fail before, with measurements taken over hours and hours? Gyro drift. Ideally, the zero point of the measurement would be zero DN, but we are happy if the zero point is just constant. But it's not. Temperature changes and other unmeasured effects cause the zero point to drift, and when measuring for hours and hours, this gyro drift swamps the signal I am trying to measure. To get a good rotation measurement, you want as many samples as possible, but taken over a relatively short time such that gyro drift is small.
So, back to the review. The MPU sensor is kind of noisy, with 11DN noise per sample, but can be read out sufficiently quickly and has sufficiently small gyro drift that it can measure the rotation of the Earth.
SPI is a nice, simple, uncomplicated way of communicating between two or more embedded devices. Set a couple of registers defining clock rate, phase, and polarity, and you are ready to go at up to about 10Mb/s. It's a convenient way to talk to microSD cards, accelerometers, basically anything on board with an embedded device. Lots of device-defined protocols can be layered on top of it to do anything the host and device agree to.
USB is a nice, COMPLICATED way of communicating between a host and multiple devices, and multiple applications within the devices. It's not just a bus protocol, it's practically a network in itself. This has its advantages and drawbacks. If my device learns how to speak Mass Storage, any host computer in the world can use it. But, it is considerably more complicated. I can't just look up in a reference guide and bit-bang a protocol out like I can with SPI or I2C.
USB is in fact a stack of protocols, much like HTTP/TCP/IP/Ethernet. Some layers are handled by the hardware autonomously, some need the cooperation of the hardware and the firmware, and some is up to the firmware completely.
The USB project I had been working off of, LPCUSB, is a set of C routines with no readily apparent structure. You can trace through the handlers, to find handlers on top of handlers and handlers all the way down. For one thing, there is code just to work with the USB hardware, then there is code to implement the mass storage class and then code to implement the serial port class. Much of the interaction between these is through callbacks. In reorganizing it into C++, I had the ideal that the device could operate both as mass storage and serial at the same time. There would be a low-level USB class, and then on top of that, a Mass Storage class, and separately a Serial class, which could both be active at the same time.
I am going to abandon that idea for now. I don't know enough about the stack to do this yet. So, we do a USB class with several abstract virtual methods, then an MSC subclass which implements the virtuals purely as mass storage, without worrying about sharing. Likewise, we are going to have a USB control endpoint handler, then a MSC subclass which does what is needed for MSC.
Everyone else was doing it, so I might as well give it a try also. Here's my use case: I want to compress the C++ source code and anything else needed to rebuild my firmware (mostly Makefiles) into one tight little package, then append that package to the firmware itself. Naturally smaller is better. Especially I would like the Bootloader++ (I'll explain it when I'm ready to publish, but its a bootloader for a Logomatic-type circuit which handles fat32 and sdhc) code and source pack to fit within the 64kiB it has allocated for itself.
So, the test case. I already have a rule in my makefile to pack the code: $(TARGET).tar.$(TAR_EXT): $(ALLTAR) $(CC) --version --verbose > /tmp/gccversion.txt 2>&1 tar $(TAR_FORMAT)cvf $(TARGET).tar.$(TAR_EXT) -C .. $(addprefix $(TARGETBASE)/, $(ALLTAR)) /tmp/gccversion.txt
I'm quite proud of the latter, as it packs the archive into a normal object file, which my linker script makes sure gets packed into the final firmware image, with symbols bracketing it so I can dump just the source code bundle.
Anyway, we will look at our challengers:
No compression, just a tar file. This one is actually a bit bigger than the total of the file sizes
gzip, the old standard, both with no special flags and with the -9 option
compress, the really old standard .Z file using the (expired) patented LZW algorithm
bzip2, the second generation compresion algorithm notable for both better compression and longer compression time than gzip, used both with no special flags and with the -9 option
Lempel-Ziv-Markov algorithm, implemented as the Ubuntu command lzip and xz. third generation compression algorithm, once again better compression, once again longer time
lzop, a compressor optimized for speed and memory consumption rather than size
PKZIP, implemented via the zip command available in Ubuntu. This might not be a fair test, as it is not compressing the TAR file, but is in fact using its own method to compress each file individually. So, it has an index, plus each file is compressed anew, meaning there is no advantage from the previous file's compression.
7z, implemented via the 7z command available in Ubuntu. Same notes as with PKZIP.
zpaq, a compressor which at each step tries several methods and picks the best. This one takes a monumental amount of time and memory, but seems to be worth it if minimum file size is the goal.
So, we notice a couple of things. One, sometimes -9 doesn't improve things measurably, and sometimes makes things worse. Next, zpaq rocks out loud as far as compressing C++ source code. It's still larger than the firmware binary image, which is 12423 bytes. It might take more time and more memory than any other compressor, but all that time and memory is in a beefy desktop machine, and not in the Loginator.
The discovery by Kepler of his laws of planetary motion is one of the more amazing bits of observational science, made more amazing by the lack of tools which he had to work with. But, that's not our gem of the week. Instead, we will see how Newton deduced that there is such a concept as universal gravitation, and proved that it worked. Actually we won't see how he did it, but we will see how it can be done with modern techniques such as vectors.
I am going to present a new feature to all my 0 readers - the "Gem of the Week". This is a reprise of a sometime feature on my old private blog, "Chemical of the Day". I am expanding the topic somewhat from chemicals to anything I find interesting. None of these are necessarily news, but they might be.
Some people have to keep secrets because they are legally obligated. This includes any government classified information. Boy am I happy I don't have to deal with that headache. I bet Robert did.
Some people have to keep secrets because they are contractually obligated. Some projects LASP works on are with customers who treat some aspects as proprietary. For instance, I was brought in on Sentinel long before it was announced, in October of last year. Ball, perhaps under orders from B612, required us to keep the mission proprietary. It is a really cool mission, and I hated not being able to talk about it for months on end.
I keep some secrets because the time is not yet right to publish. I have something cool in mind for the Loginator, but I don't want to shoot my mouth off before I know that it is going to happen. So, watch this space...
My C++ification of the Loginator code continues. As noted below, I have the startup code now in full C++ (with 18 lines of inline asm), and I have overthrown the tyranny of main() (that sounds familiar, have I written on this topic before?). I have taken Roland Riegel's sd_raw driver and heavily modified and simplified it. Basically I made it a pure block device. I have dropped all the buffering. You can open an SD card (SDHC fully supported), read a block, write a block, and get the card info.
I looked into extending c++ifying the partition and fat32 driver, but it looked too complicated and messy. One of the things I am dead set against is dynamic memory allocation in an embedded process. What if it fails? When that happens, the software crashes (it wouldn't ask for memory if it didn't desperately need it) and when that happens, it is a good possibility that the device it is flying crashes too.
So, I get to write a fat32 driver myself. Once again, only whole blocks at a time. And to start with, only that which the USB bootloader and Logomatic need: read a file, write a file, delete a file. Also to start with, we fully support FAT32, but do not support long filenames.
One area where I am going to get myself in trouble is writing the file. Sometimes when you write a file, you have to change the file allocation table. When you do so, you need to read the sector containing the change, make the change, then write the new sector. This is all easy, but you need a buffer to do it. Also, you will need to read the table to find the next cluster. What buffer do you use? I know that the LPC2148 is not really memory-limited, but it still seems a waste to set aside a whole block buffer for this.
I started by writing a partition driver. You pass it an open and started SD object and a partition number, and it reads the partition table to get the info for that partition. From then on, you use the partition object to read and write blocks.